#!/usr/bin/env python3
"""Local DPW review analysis. Python 3 standard library only; source files read-only.
Run from anywhere: python3 community-build/scripts/speed_time_of_day.py
Outputs: community-build/outputs/speed-time-of-day-review/ (or --output PATH).
Percentiles use linear interpolation, matching pandas' default quantile method.
"""
import argparse
import csv
import hashlib
import json
import math
from collections import defaultdict
from datetime import date
from pathlib import Path
from statistics import mean, median
from xml.sax.saxutils import escape
ROOT = Path(__file__).resolve().parent.parent
PHASES = ('PRE', 'POST')
STRATA = ('Weekday AM', 'Weekday PM', 'Weekend PM')
def read(path):
with path.open(newline='') as f:
return list(csv.DictReader(f))
def quantile(x, p):
x = sorted(x)
i = (len(x) - 1) * p
lo, hi = math.floor(i), math.ceil(i)
return x[lo] + (x[hi] - x[lo]) * (i - lo)
def stats(rows):
x = [r['speed'] for r in rows]
return dict(n=len(x), sessions=len({r['session_id'] for r in rows}),
dates=len({r['date'] for r in rows}), mean_mph=mean(x) if x else None,
median_mph=median(x) if x else None,
p85_mph=quantile(x, .85) if x else None,
over25_count=sum(v > 25 for v in x),
over25_pct=100 * sum(v > 25 for v in x) / len(x) if x else None,
min_mph=min(x) if x else None, max_mph=max(x) if x else None)
def grouped(rows, keys):
groups = defaultdict(list)
for r in rows:
groups[tuple(r[k] for k in keys)].append(r)
return [dict(zip(keys, k), **stats(v)) for k, v in sorted(groups.items())]
def write_csv(path, rows):
with path.open('w', newline='') as f:
w = csv.DictWriter(f, fieldnames=list(rows[0]))
w.writeheader()
for row in rows:
w.writerow({k: round(v, 6) if isinstance(v, float) else v for k, v in row.items()})
def contrast(rows, label):
a, b = (stats([r for r in rows if r['phase'] == ph]) for ph in PHASES)
assert a['n'] and b['n'], label
return dict(comparison=label, pre_n=a['n'], post_n=b['n'],
pre_dates=a['dates'], post_dates=b['dates'],
pre_mean_mph=a['mean_mph'], post_mean_mph=b['mean_mph'],
post_minus_pre_mph=b['mean_mph'] - a['mean_mph'],
pre_p85_mph=a['p85_mph'], post_p85_mph=b['p85_mph'],
pre_over25_pct=a['over25_pct'], post_over25_pct=b['over25_pct'],
over25_change_pp=b['over25_pct'] - a['over25_pct'])
def chart(path, title, labels, pre, post, unit, ceiling, footnote, comparisons):
# Exported vector chart, with explicit units, zero baseline and denominators in tables.
w, h = 980, 660
parts = [f'']
path.write_text('\n'.join(parts) + '\n')
def main():
parser = argparse.ArgumentParser(description=__doc__)
parser.add_argument('--release', type=Path, default=ROOT / 'outputs/speed-data-public')
parser.add_argument('--output', type=Path, default=ROOT / 'outputs/speed-time-of-day-review')
args = parser.parse_args()
release, out = args.release.resolve(), args.output.resolve()
assert out != release and release not in out.parents, 'Do not write into the public release'
out.mkdir(parents=True, exist_ok=True)
hashes = json.loads((release / 'release-hashes.json').read_text())
verified = {}
for filename, expected in hashes.items():
actual = hashlib.sha256((release / filename).read_bytes()).hexdigest()
assert actual == expected, f'Release integrity failed: {filename}'
verified[filename] = actual
sessions = read(release / 'survey_sessions_public.csv')
ses = {r['session_id']: r for r in sessions}
assert len(ses) == len(sessions) == 30
source = read(release / 'speed_observations_public.csv')
assert len({r['observation_id'] for r in source}) == len(source)
build = date(2026, 4, 25)
rows, flagged = [], []
for r in source:
s = ses[r['session_id']]
assert r['date'] == s['date']
phase = s['intervention_phase'].split()[0]
d = date.fromisoformat(r['date'])
assert d.strftime('%A') == s['day_of_week']
assert (d < build) == (phase == 'PRE') and d != build
period = s['time_period'] or 'Unknown'
weekend = d.weekday() >= 5
stratum = ('Weekend' if weekend else 'Weekday') + ' ' + period if period != 'Unknown' else 'Unknown'
row = dict(session_id=r['session_id'], date=r['date'], phase=phase,
time_period=period, stratum=stratum, day_of_week=s['day_of_week'],
direction=r['direction'] or 'Unknown', speed=int(r['speed_mph']))
(flagged if r['data_quality_flag'].strip() else rows).append(row)
assert len(source) == 8988 and len(rows) == 8986 and len(flagged) == 2
assert len([r for r in rows if r['phase'] == 'PRE']) == 3880
assert len([r for r in rows if r['phase'] == 'POST']) == 5106
assert len([r for r in rows if r['time_period'] == 'Unknown']) == 286
coverage = []
for s in sessions:
rr = [r for r in rows if r['session_id'] == s['session_id']]
ff = [r for r in flagged if r['session_id'] == s['session_id']]
d = date.fromisoformat(s['date'])
notes = []
if s['session_id'] == 'Session 022': notes.append('No recorded period; 1:35 has no meridiem; excluded from period comparisons')
if s['session_id'] == 'Session 025': notes.append('PM label retained; 00:00 to 1:00 is not a usable clock window')
if s['date'] == '2026-04-23': notes.append('Overlapping sessions on one date; independence and repeated vehicle sampling unverified')
if not s['end_time']: notes.append('End time missing')
if s['session_id'] == 'Session 018': notes.append('Only 25 minutes recorded')
if not rr: notes.append('No speed readings; excluded from means, never entered as zero')
coverage.append(dict(session_id=s['session_id'], phase=s['intervention_phase'].split()[0],
date=s['date'], day_of_week=s['day_of_week'],
time_period=s['time_period'] or 'Unknown',
stratum=rr[0]['stratum'] if rr else ('Weekend' if d.weekday() >= 5 else 'Weekday') + ' ' + (s['time_period'] or 'Unknown'),
recorded_start=s['start_time'], recorded_end=s['end_time'],
observed_vehicles=len(rr)+len(ff), flagged_readings=len(ff),
**stats(rr), notes='; '.join(notes)))
write_csv(out / 'session_coverage.csv', coverage)
write_csv(out / 'phase_summary.csv', grouped(rows, ['phase']))
write_csv(out / 'period_summary.csv', grouped(rows, ['time_period', 'phase']))
write_csv(out / 'stratum_summary.csv', grouped(rows, ['stratum', 'phase']))
write_csv(out / 'day_of_week_summary.csv', grouped(rows, ['stratum', 'day_of_week', 'phase']))
write_csv(out / 'direction_summary.csv', grouped(rows, ['stratum', 'direction', 'phase']))
dates = grouped(rows, ['stratum', 'date', 'phase'])
write_csv(out / 'date_stratum_summary.csv', dates)
contrasts = [contrast(rows, 'All readings (includes unknown PRE period)')]
for period in ('AM', 'PM'):
contrasts.append(contrast([r for r in rows if r['time_period'] == period], period))
for st in STRATA:
contrasts.append(contrast([r for r in rows if r['stratum'] == st], st))
write_csv(out / 'comparisons.csv', contrasts)
sensitivities = []
for st in STRATA:
rr = [r for r in rows if r['stratum'] == st]
by_day = grouped(rr, ['phase', 'day_of_week'])
shared = sorted(set(r['day_of_week'] for r in rr if r['phase'] == 'PRE') &
set(r['day_of_week'] for r in rr if r['phase'] == 'POST'))
for method, units in [('Equal weight per nonempty session', grouped(rr, ['phase', 'session_id'])),
('Equal weight per collection date', grouped(rr, ['phase', 'date'])),
('Equal weight per shared day of week', [r for r in by_day if r['day_of_week'] in shared])]:
aa, bb = ([r for r in units if r['phase'] == ph] for ph in PHASES)
pre, post = mean(r['mean_mph'] for r in aa), mean(r['mean_mph'] for r in bb)
sensitivities.append(dict(stratum=st, method=method, pre_units=len(aa), post_units=len(bb),
pre_mean_mph=pre, post_mean_mph=post, post_minus_pre_mph=post-pre,
notes='Shared days: ' + ', '.join(shared) if 'shared' in method else 'Descriptive weighting sensitivity, not independent replicates'))
# Omit a date in either phase; recompute the vehicle-weighted contrast.
deltas = []
for ph in PHASES:
for dd in sorted({r['date'] for r in rr if r['phase'] == ph}):
reduced = [r for r in rr if not (r['phase'] == ph and r['date'] == dd)]
deltas.append(contrast(reduced, st)['post_minus_pre_mph'])
sensitivities.append(dict(stratum=st, method='Leave one phase/date out: delta range',
pre_units='', post_units='', pre_mean_mph='', post_mean_mph='',
post_minus_pre_mph='', notes=f'{min(deltas):.3f} to {max(deltas):.3f} mph; sensitivity range, not a confidence interval'))
write_csv(out / 'weighting_sensitivity.csv', sensitivities)
extra = [contrast([r for r in rows if r['stratum'] == 'Weekday PM' and r['date'] != '2026-04-23'],
'Weekday PM excluding all PRE April 23 overlapping sessions')]
inferred = [dict(r, time_period='PM', stratum='Weekend PM') if r['session_id'] == 'Session 022' else r for r in rows]
extra.append(contrast([r for r in inferred if r['stratum'] == 'Weekend PM'],
'Weekend PM if Session 022 is assumed PM (unverified)'))
extra.append(contrast(rows + flagged, 'All readings including flagged (sensitivity only)'))
write_csv(out / 'other_sensitivity.csv', extra)
# Reconcile every nonempty session against all r2 session statistics, including thresholds.
old = {r['session_id']: r for r in read(release / 'analysis/session_speed_summary.csv')}
for c in coverage:
if not c['n']: continue
a = old[c['session_id']]
for mine, theirs in [('n', 'observations'), ('mean_mph', 'average_speed'),
('median_mph', 'median_speed'), ('p85_mph', 'p85_speed'),
('min_mph', 'min_speed'), ('max_mph', 'max_speed')]:
assert abs(c[mine] - float(a[theirs])) <= .000501, (c['session_id'], mine)
assert abs(c['over25_pct']/100-float(a['share_above_25_mph'])) <= .000501
by_name = {r['comparison']: r for r in contrasts}
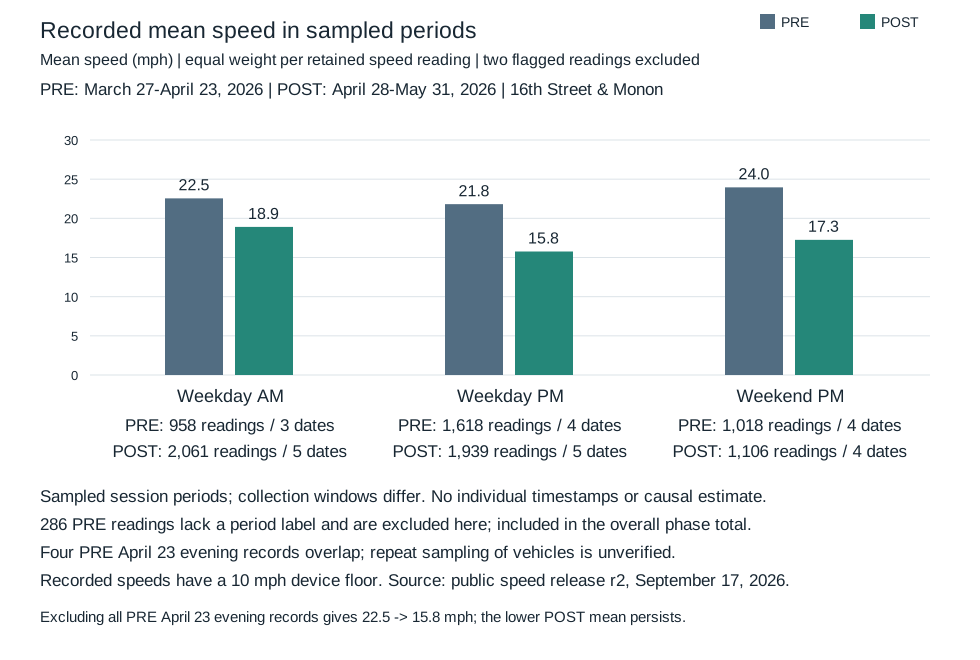
chart(out / 'mean_speed.svg', 'Recorded mean speed in sampled periods', list(STRATA),
[by_name[st]['pre_mean_mph'] for st in STRATA], [by_name[st]['post_mean_mph'] for st in STRATA],
'Mean speed (mph)', 30, 'Excluding all PRE April 23 evening records gives 22.5 -> 15.8 mph; the lower POST mean persists.', [by_name[st] for st in STRATA])
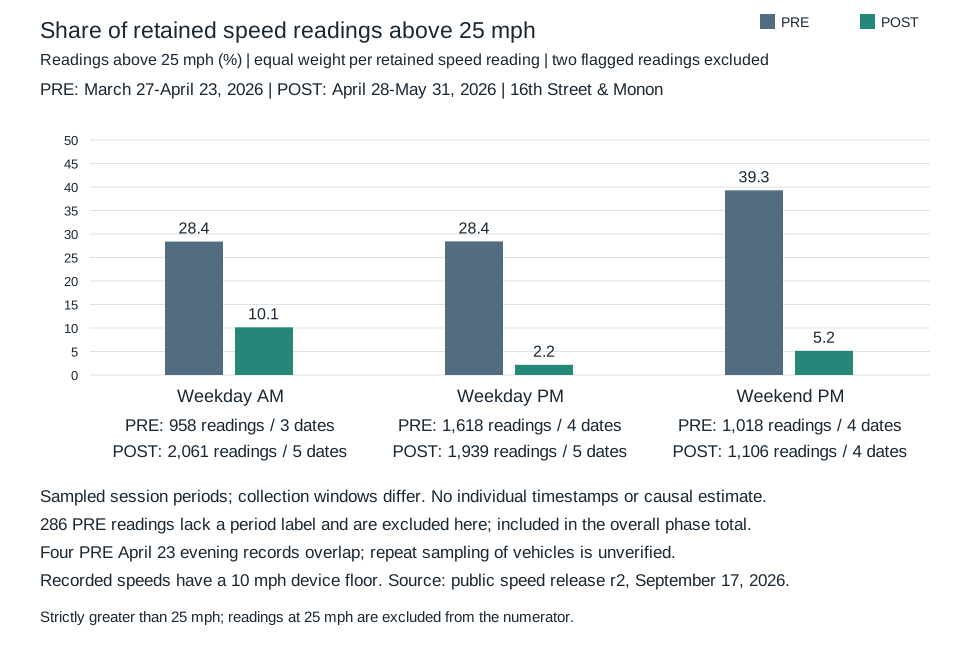
chart(out / 'over25_share.svg', 'Share of retained speed readings above 25 mph', list(STRATA),
[by_name[st]['pre_over25_pct'] for st in STRATA], [by_name[st]['post_over25_pct'] for st in STRATA],
'Readings above 25 mph (%)', 50, 'Strictly greater than 25 mph; readings at 25 mph are excluded from the numerator.', [by_name[st] for st in STRATA])
summary = ['# Time-of-day speed comparison: local DPW review draft', '',
'POST recorded speeds were lower in the sampled weekday mornings, weekday evenings and weekend afternoons. The table describes retained readings collected in those periods. It does not represent every hour of the day, match exact PRE/POST collection windows, or isolate the installation\'s causal effect.', '',
'| Recorded period | PRE n / dates | POST n / dates | Mean PRE -> POST (mph) | Change (mph) | p85 PRE -> POST (mph) | Above 25 mph PRE -> POST |',
'|---|---:|---:|---:|---:|---:|---:|']
for key in STRATA:
c = by_name[key]
summary.append(f"| {key} | {c['pre_n']:,} / {c['pre_dates']} | {c['post_n']:,} / {c['post_dates']} | {c['pre_mean_mph']:.1f} -> {c['post_mean_mph']:.1f} | {c['post_minus_pre_mph']:.1f} | {c['pre_p85_mph']:.1f} -> {c['post_p85_mph']:.1f} | {c['pre_over25_pct']:.1f}% -> {c['post_over25_pct']:.1f}% |")
summary += ['', '## What DPW requested', '',
'In the [September 17 call transcript](../../meeting-notes/call-with-dpw-september-17-2026.txt), Chris at 36:17 (lines 469-472) asks for individual speed studies to inspect trends at certain times of day and collection points, for sharing with DPW teams internally. "Collection points" is ambiguous: the transcript does not define separate geographic sites, matched clock hours, or a weighting method. The released location is one normalized intersection; these data do not establish comparisons between distinct geographic collection points.', '',
'Carlos\'s [local follow-up draft](../../dpw-followup-email-2026-09-17.md) separately promises to break speed data out by time of day rather than only aggregate before/after numbers. That is Carlos\'s proposed response to the request, not evidence that DPW prescribed these three groups or the weighting checks. The September 18 sent follow-up is established by the delegated brief; this task uses the local draft for its wording, without re-reading the sent message.', '',
'The three sampled-period rows above answer the descriptive time-of-day part. The session table below supplies the individual collection context. Supporting weighting checks belong in an appendix; they are not the central deliverable requested by DPW.', '',
'## Collection windows and limits to comparison', '',
'- Wednesday AM has no recorded PRE/POST clock overlap: PRE April 1 is 08:05-08:30; POST May 13 is 08:34-09:34. The shared weekday label does not make these matched morning observations.',
'- Tuesday AM also varies: PRE shifts include 08:39-09:42 and 07:35-08:35; POST shifts start at 07:30 or 08:09. Weekday evening starts and endpoints vary too. No exact-window matching is performed, because individual readings have no clock timestamps.',
'- Four nonempty PRE April 23 evening session records overlap, plus one empty record. They are not five independent evenings. Unique record IDs do not prove distinct vehicles; repeated sampling of a vehicle cannot be checked. No silent deduplication is performed. The empty session contributes no readings and is never entered as a zero-speed mean.',
'- Session 022 has 286 PRE readings and start "1:35" without a period or endpoint. It remains unknown in the main analysis. Session 025 has a PM label but "00:00" to "1:00" clock text; its recorded PM classification is retained, with the clock interval unverified. Other missing endpoints remain visible in the session table.',
'- These are observations in sampled periods, not hourly full-day patterns or trends at distinct geographic points. Time, weather, observers, vehicle mix and traffic conditions were not held constant. Weighting cannot adjust away that confounding. No causal, statistical-significance or injury-risk claim is made.', '',
'## Session-level collection table', '',
'Dates, clocks and periods below reproduce the recorded fields; unlabeled clock text is not silently converted. n is retained speed readings. A dash marks a statistic undefined for an empty session. [session_coverage.csv](session_coverage.csv) contains full-precision statistics, flagged-reading counts and handling notes.', '',
'| Phase | Date | Session | Recorded period | Recorded start -> end | n | Mean (mph) | p85 (mph) | Above 25 mph |',
'|---|---|---|---|---|---:|---:|---:|---:|']
for c in sorted(coverage, key=lambda c: (0 if c['phase'] == 'PRE' else 1, c['date'], c['session_id'])):
mm = f"{c['mean_mph']:.1f}" if c['n'] else '-'
pp = f"{c['p85_mph']:.1f}" if c['n'] else '-'
above = f"{c['over25_count']}/{c['n']} ({c['over25_pct']:.1f}%)" if c['n'] else '-'
summary.append(f"| {c['phase']} | {c['date']} | {c['session_id']} | {c['time_period']} | {c['recorded_start'] or '(missing)'} -> {c['recorded_end'] or '(missing)'} | {c['n']} | {mm} | {pp} | {above} |")
summary += ['', '## Coverage and definitions', '',
'- Source: public speed release r2 (September 17, 2026), not CIC\'s separate automated counter dataset. All release hashes verified.',
'- PRE: March 27-April 23, 2026, before the April 25 installation; 16 session records, 15 with readings, 9 dates. POST: April 28-May 31, 14 sessions with readings, 11 dates. These are irregular samples, not continuous four-week monitoring.',
'- 8,988 observed vehicles; 8,986 retained speed readings: 3,880 PRE and 5,106 POST. Two POST May 7 PM readings (78 and 51 mph) remain excluded under the existing r2 flags; neither source record was changed.',
'- AM + PM cover 3,594 PRE readings and all 5,106 POST readings. Session 022 has 286 PRE readings without a recorded period. It remains in the phase total and is excluded from time-of-day contrasts. Its start "1:35" alone is insufficient to assign a period.',
'- Dates and shift clocks are treated as Indianapolis local wall time (America/Indiana/Indianapolis; spring dates fall in daylight time). The CSV contains no explicit time zone or UTC offset; local time is an analysis assumption to confirm with the collector. No timezone conversion or hourly binning is performed.',
'- AM means the recorded session AM label; sampled weekdays start roughly 07:30-08:39. Weekday PM starts roughly 16:10-17:37; weekend PM generally starts 13:00-14:31. PM is therefore not one comparable rush-hour window. One PRE Sunday has "00:00" to "1:00" with a PM label: its recorded PM classification is retained but its clock interval is unverified.',
'- Time belongs to the session, not to each vehicle. There are no per-vehicle timestamps. Start/end clocks are inconsistent, some missing, and forms can contain elapsed times instead of clock times. Durations are not summed into exposure hours or used for speed weighting. One PRE AM session is only 25 minutes.',
'- Main statistics give each retained vehicle speed equal weight. The above-25 numerator counts speeds strictly >25; the denominator is retained speeds in that row. Medians and 85th percentiles pool readings with linear interpolation. They are not averages of session percentiles.',
'- The instrument recorded slower vehicles at a 10 mph floor according to the existing study notes. These are recorded-speed means, with the same known floor in both phases.', '',
'## Appendix A: supporting checks of mean speed', '',
'These are descriptive mean sensitivities, not confidence intervals or adjusted causal estimates. They do not reweight the reported percentiles or above-25 shares. Their purpose is to check whether the direction and size of the mean comparison depend on collection weights; DPW did not request these particular methods.', '',
'- Baseline: every retained speed reading has equal weight. A collection with 400 readings contributes four times as much as one with 100.',
'- Equal session weight: calculate each nonempty session mean, then average those means equally. This describes the average session mean and depends on how collections were split into records; four April 23 records receive four session weights despite overlapping.',
'- Equal date weight: pool readings within each phase/date/period, calculate its mean, then average dates equally. This describes the average sampled-date mean and gives April 23 one date weight. It does not remove any possible repeated vehicle readings within that date.',
'- Equal shared-weekday weight: retain only days of the week present in both phases, pool readings within each phase/weekday/period, then average weekday means equally. This changes both weights and included observations. Shared days are Tuesday/Wednesday for AM, Tuesday/Thursday for weekday PM, and Saturday/Sunday for weekend PM. For weekday PM, removing unmatched PRE Wednesday/Friday as well as changing weights moves the mean difference from -6.0 to -3.1 mph. It is not automatically a better-adjusted estimate and does not match weather, exact clocks, traffic mix, observers or seasonal conditions.',
'- [weighting_sensitivity.csv](weighting_sensitivity.csv) also reports a leave-one-date-out range: omit one date in one phase at a time and recompute the pooled-reading mean difference. This is a sensitivity range, not a confidence interval. Few dates and overlapping collections make vehicle-level independence tests misleading.',
'- [direction_summary.csv](direction_summary.csv) preserves missing/undefined directions as separate categories. No adjustment here recovers unrecorded individual times or establishes distinct geographic collection points.', '',
'| Stratum | Weighting | PRE mean | POST mean | Change (mph) |',
'|---|---|---:|---:|---:|']
for s in sensitivities:
if s['pre_mean_mph'] == '': continue
summary.append(f"| {s['stratum']} | {s['method']} | {s['pre_mean_mph']:.1f} | {s['post_mean_mph']:.1f} | {s['post_minus_pre_mph']:.1f} |")
summary += ['', 'Additional sensitivity checks:', '']
for c in extra:
summary.append(f"- {c['comparison']}: {c['pre_mean_mph']:.1f} -> {c['post_mean_mph']:.1f} mph (change {c['post_minus_pre_mph']:.1f}).")
summary += ['', '## Appendix B: pooled recorded AM/PM labels', '',
'These aggregates reproduce the existing AM/PM breakdown. PM combines weekday evenings with weekend afternoons, so the three sampled-period rows at the top are more informative for review.', '',
'| Recorded label | PRE n / dates | POST n / dates | Mean PRE -> POST (mph) | Change (mph) |',
'|---|---:|---:|---:|---:|']
for key in ('AM', 'PM'):
c = by_name[key]
summary.append(f"| {key} | {c['pre_n']:,} / {c['pre_dates']} | {c['post_n']:,} / {c['post_dates']} | {c['pre_mean_mph']:.1f} -> {c['post_mean_mph']:.1f} | {c['post_minus_pre_mph']:.1f} |")
summary += ['', '## Review and reproduction', '',
'Run from /Users/calemus/projects/16xmonon:', '',
'```sh', 'python3 community-build/scripts/speed_time_of_day.py', '```', '',
'Python 3 standard library only. All output CSVs use full precision rounded to six decimals; displayed results use one decimal. Source files are read only. verification.json records input hashes, checks and output hashes. SVG charts are standalone vector files; preview.html displays both charts locally.', '',
'Small remaining decision: confirm the assumed local timezone and, if possible, the missing/ambiguous session times and April 23 collection layout. The current draft can be reviewed without resolving those gaps because it keeps them visible. Carlos should review the summary before anything is sent or published. External documents, email, the existing release, and raw records were not edited.', '']
(out / 'README.md').write_text('\n'.join(summary))
(out / 'preview.html').write_text('Speed review plots
Time-of-day speed review
Local draft. Read README.md for denominators, coverage and limitations.
 \n')
output_names = ['session_coverage.csv', 'phase_summary.csv', 'period_summary.csv', 'stratum_summary.csv',
'day_of_week_summary.csv', 'direction_summary.csv', 'date_stratum_summary.csv',
'comparisons.csv', 'weighting_sensitivity.csv', 'other_sensitivity.csv',
'mean_speed.svg', 'over25_share.svg', 'README.md', 'preview.html']
manifest = dict(source_release='r2 2026-09-17', input_hashes=verified,
script_sha256=hashlib.sha256(Path(__file__).read_bytes()).hexdigest(),
checks=['All release hashes match', 'Unique observation IDs', 'Session joins complete',
'Observation/session dates match', 'Weekday labels match dates', 'PRE/POST straddle April 25',
'8988 vehicles / 8986 speeds / 2 flagged', '3880 PRE / 5106 POST',
'286 unknown-period PRE readings', 'All 29 nonempty r2 session summaries reconciled'],
output_hashes={n: hashlib.sha256((out / n).read_bytes()).hexdigest() for n in output_names})
(out / 'verification.json').write_text(json.dumps(manifest, indent=2) + '\n')
print(f'Verified {len(verified)} release hashes and 29 nonempty session summaries. Outputs: {out}')
print((out / 'README.md').read_text().split('## Coverage')[0])
if __name__ == '__main__':
main()